Matthew Bronars

I am a third-year PhD student in the Robotics Institute at Carnegie Mellon University, advised by Katerina Fragkiadaki. I work on world models for robotics, studying how 3D representations, massively scaled simulation, and test-time search can make robots more effective and more generalizable.

Before CMU, I received my MS in Computer Science from Georgia Tech (2024), where I was advised by Danfei Xu and worked on imitation learning and legible robot motion. I received my BS in EECS and Mechanical Engineering from UC Berkeley (2022). I have also been a computer vision intern at Schlumberger-Doll Research (2021) and a machine learning intern at Symbotic (2023).

Photo of Matthew Bronars

Research

I want robots that imagine and reason about the consequences of their actions before they act. My current work builds generative world models that predict physical dynamics directly in 3D and uses them to plan contact-rich manipulation. I am also interested in faster planning and inference with diffusion and flow models, real-world policy adaptation with reinforcement learning, and runtime safety for robots working around people. I have also worked on learning from large offline demonstration datasets and on generating legible robot motion that leads to better human robot collaboration.

I am looking for research internships for summer 2027. If you think I could be a good fit for your team, please reach out by email at mbronars@andrew.cmu.edu.

Publications and Projects

Representative works are highlighted.

Particle letters G, P, W, M▶ click for full teaser
GPWM: Modeling the World as 3D Particle Motion Robert Ren*, Matthew Bronars*, He Zhu, Yikai Tang, Jianing Zhang, Sergey Zakharov, Pavel Tokmakov, Katerina Fragkiadaki *Equal contribution, ordered by coin flip
arXiv 2026 · Spotlight, CoRL 2026 Workshop “Do Robots Need World Models?”

Keywords: World Models, 3D Dynamics, Generative Models, Planning

TL;DR: We train a 3D particle world model that achieves state-of-the-art dynamics prediction across rigid, deformable, cloth, and granular materials. Optimizing the model’s latent noise lets the same generative world model serve as an effective planner for contact-rich tasks.
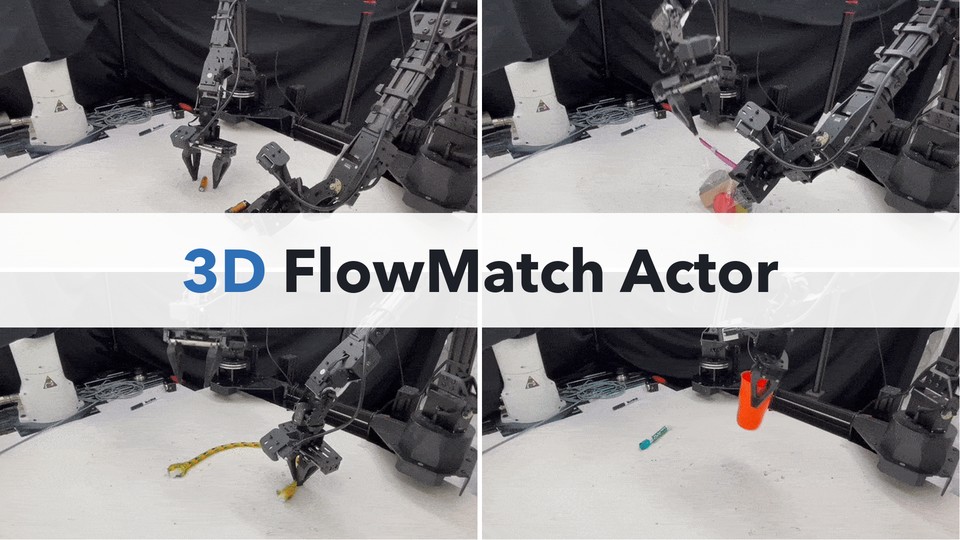
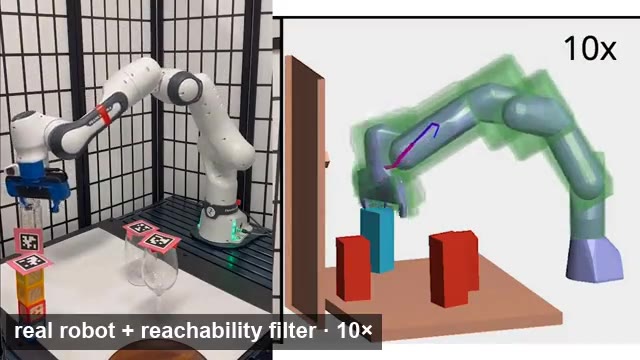
3D FlowMatch Actor: flow-matching trajectories and real bimanual tasks▶
3D FlowMatch Actor: Unified 3D Policy for Single- and Dual-Arm Manipulation Nikolaos Gkanatsios*, Jiahe Xu*, Matthew Bronars, Arsalan Mousavian, Tsung-Wei Ke, Katerina Fragkiadaki IROS 2026

Keywords: Imitation Learning, Flow Matching, 3D Policies, Bimanual Manipulation

TL;DR: A flow-matching robot policy that uses 3D relative attention between action and visual tokens. It sets a new state of the art on bimanual PerAct2 and trains and runs over 30× faster than previous 3D diffusion-based policies.

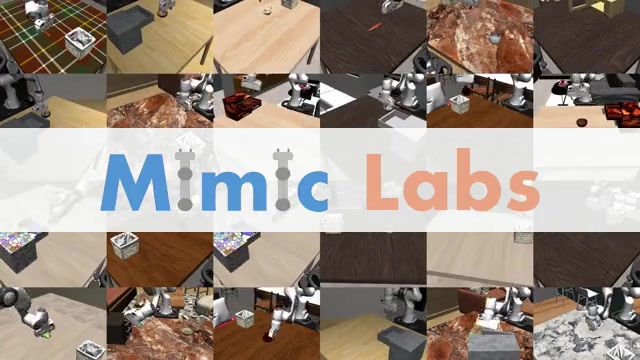
Grid of MimicLabs simulated scenes▶
What Matters in Learning from Large-Scale Datasets for Robot Manipulation? Vaibhav Saxena, Matthew Bronars*, Nadun Ranawaka Arachchige*, Kuancheng Wang, Woo Chul Shin, Soroush Nasiriany, Ajay Mandlekar, Danfei Xu ICLR 2025

Keywords: Imitation Learning, Large Scale Robotic Datasets, OOD Generalization

TL;DR: We develop a simulation framework for generating and evaluating common sources of variation in robotics. Through our analysis, we uncover the types of diversity that should be emphasized during future data collection and best practices for retrieving relevant demonstrations from existing datasets.

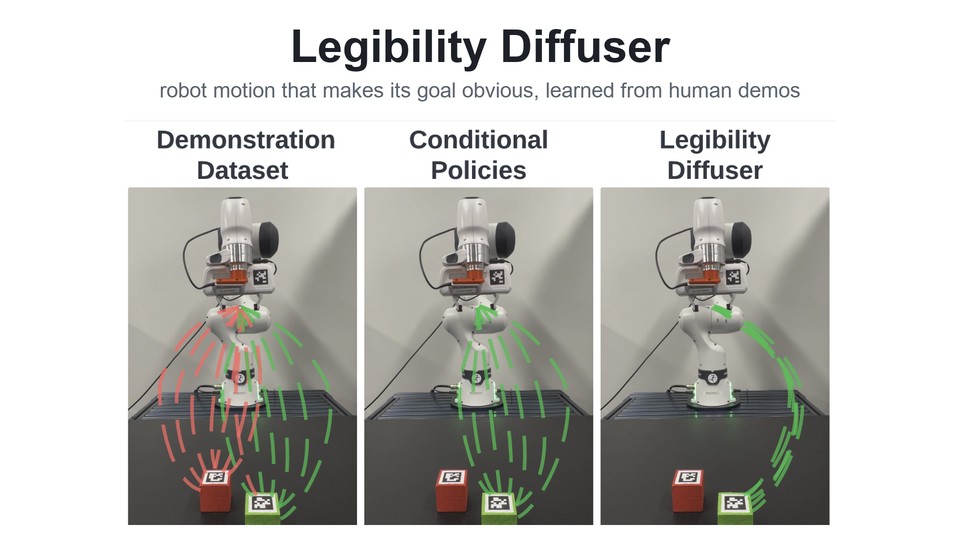
Legibility Diffuser: demonstrations, conditional policies, and legible motion▶
Legibility Diffuser: Offline Imitation for Intent Expressive Motion Matthew Bronars, Shuo Cheng, Danfei Xu RA-L 2024 (presented at ICRA 2025)

Keywords: Human Robot Interaction, Diffusion Models, Imitation Learning

TL;DR: By leveraging diffusion model guidance, Legibility Diffuser is able to clone the most legible trajectories from a dataset of multi-modal, multi-task human demonstrations.

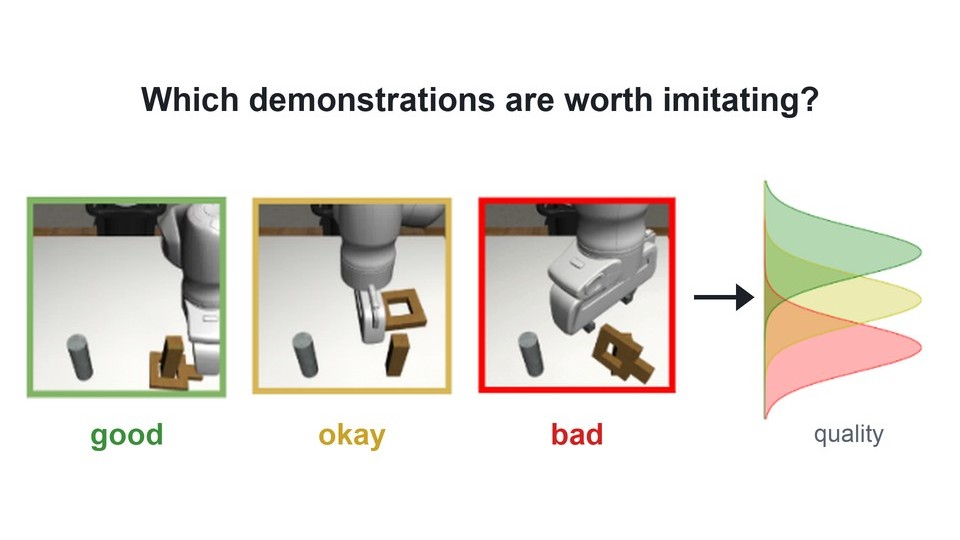
Good, okay, and bad demonstrations mapped to learned quality
Learning to Discern: Imitating Heterogeneous Human Demonstrations with Preference and Representation Learning Sachit Kuhar, Shuo Cheng, Shivang Chopra, Matthew Bronars, Danfei Xu CoRL 2023

Keywords: Imitation Learning, Preference Learning, Manipulation

TL;DR: Learning to Discern (L2D) is an imitation learning framework for learning from suboptimal demonstrations. By training a quality evaluator in a learned latent space, L2D can generalize to new demonstrators given only a small subset of labeled data.

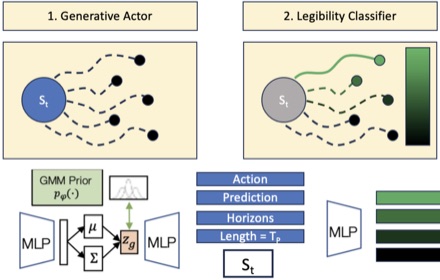
GLMM
Legible Robot Motion from Conditional Generative Models Matthew Bronars, Danfei Xu ICML Workshop on Interactive Learning from Human Feedback, 2023

TL;DR: We introduce Generative Legible Motion Models (GLMM), a framework that utilizes conditional generative models to learn legible trajectories from human demonstrations.

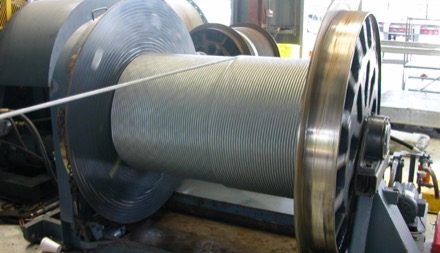
Wireline cable spool
Vision Based Wireline Cable Tracking and Anomaly Detection Matthew Bronars, Tianxiang Su, Suraj Kiran Raman, Zhandos Ombayev Schlumberger-Doll Research, 2021 · US Patent 12,406,352 B1 (granted 2025)

TL;DR: Designed a transfer learning pipeline for cable tracking and damage detection across multiple well sites.

Teaching

  • [Fa 2025] Deep Reinforcement Learning, CMU 10-703 (created an assignment on PPO and advanced policy gradient methods)
  • [Sp 2024] Deep Learning for Robotics, Georgia Tech CS 8803 DLM (created an assignment on learning from demonstrations)
  • [Fa 2023] Deep Learning, Georgia Tech CS 7643 (created an assignment on generative models)
Coursework (collapsed by default)
  • Machine Learning, UC Berkeley CS 189
  • [Fa 2022] Artificial Intelligence, Georgia Tech CS 6601
  • [Fa 2022] Computational Data Analysis, Georgia Tech CSE 6740
  • [Sp 2023] Deep Learning, Georgia Tech CS 7643
  • [Sp 2023] Human Robot Interaction, Georgia Tech CS 7633
  • [Fa 2023] Machine Learning with Limited Supervision, Georgia Tech CS 7647